A research team can rerun a paper's analysis, get the same number and still miss a consequential error in the code. In a study of quantitative social science, researchers working without ChatGPT were better at finding major coding errors than researchers working with it. The two groups were similarly successful at reproducing the published results.


The study assigned 288 researchers to 103 teams and compared three arrangements. People worked on their own, people used ChatGPT as a collaborator, or ChatGPT led with minimal human oversight. The teams tried to regenerate published findings and look for errors. They also proposed ways to check whether the findings would hold if the analysis changed.
Reproducing a number was only the first hurdle
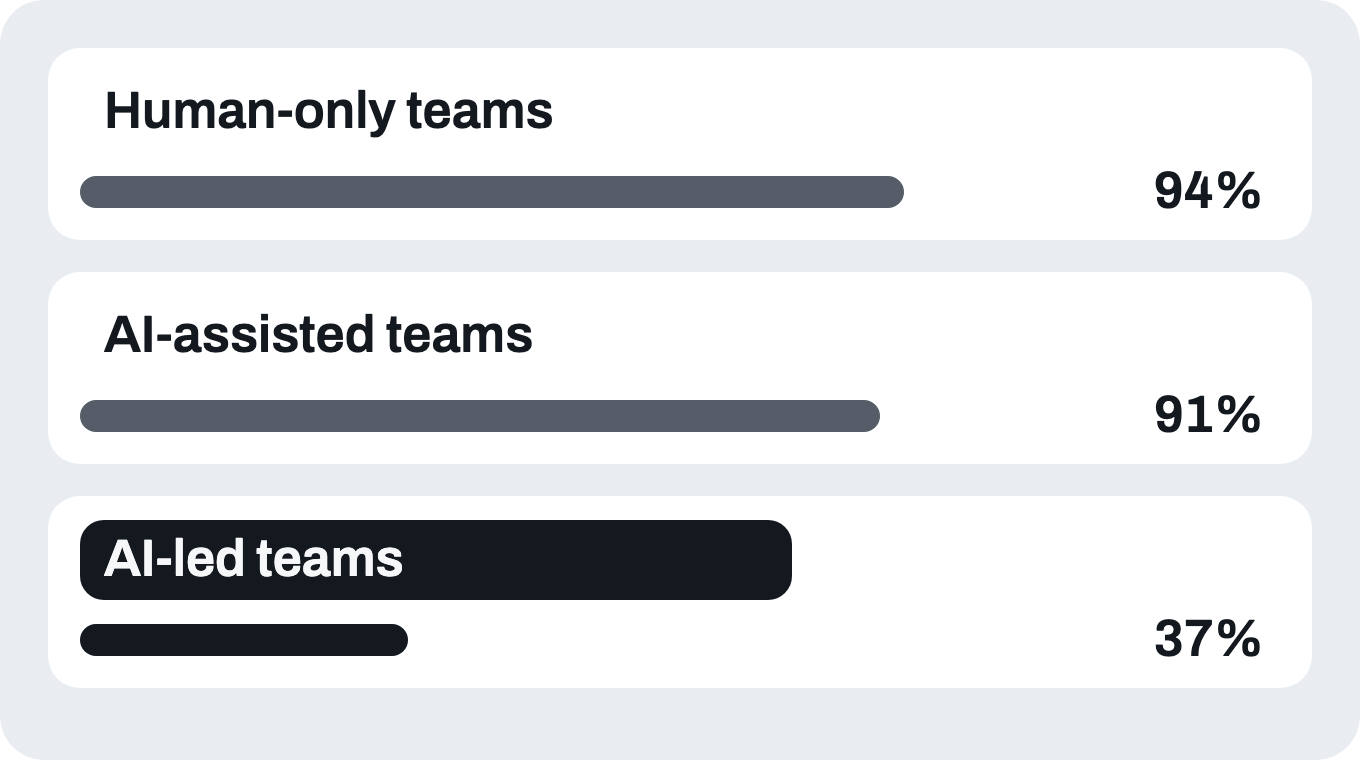
The reported reproduction rates were 94 percent for human-only teams and 91 percent for teams using ChatGPT. The AI-led teams reached 37 percent, found fewer errors and proposed weaker checks. Those rates describe the study's tasks and tools. The authors say their setup for minimal human oversight could underestimate what other autonomous systems can do.
The error result matters because reproducing a finding is only one part of checking it. A checker may need to ask whether the code used the intended observations or tested the right comparison. A scorecard that stops at getting the same answer can miss whether a team asked those questions.